Structured Test-Time Scaling: From Multi-Agent Systems to General Inference Architectures
A unified theoretical framework for structured test-time scaling, showing how topology compression, scope isolation, and decoupled verification—a three-layer structural decoupling—bypass the linear collapse of long-horizon reasoning across multi-agent systems, recursive architectures, and coding agents.
Note: This post is a work in progress and may be updated frequently. We are currently working on experiments.
Abstract
Recent empirical breakthroughs in test-time scaling—driven by Multi-Agent Systems (MAS), dynamic recursive architectures like Recursive Language Models (RLMs), and coding agents with environment feedback—have demonstrated the remarkable power of scaling compute during inference. Yet, while unstructured approaches (e.g., linear chains-of-thought) inevitably hit a mathematical ceiling due to exponentially compounding errors, the design of successful structured systems remains largely heuristic. This note proposes a unified theoretical framework to explain why these dynamic, multi-context topologies represent the future of reliable reasoning. By applying the work–span lens of parallel computation, we reveal that they bypass linear collapse via a three-layer structural decoupling: (i) Topology compresses the sequential control span from $\Theta(W)$ to $\tilde O(\log W)$; (ii) Scope isolation explicitly decouples persistent state from ephemeral context to suppress intrinsic atomic errors; and (iii) Strict verification acts as a decoupled error-correction code to truncate residual failure tails. Together, these three layers reduce the effective failure exponent from $\Theta(W)$ to $\tilde O(\log W)$. We conclude by formalizing the physical constraints—such as semantic integration limits and context hygiene—that govern this next generation of inference architectures.
Introduction
The rise of test-time scaling. The scaling-law frontier is shifting from training to inference. As the AI community tackles increasingly complex, long-horizon tasks, attention has turned to test-time scaling—investing more compute during inference to boost reasoning quality. Recent systematic studies confirm this paradigm extends to agentic settings
Structured test-time scaling beyond multi-agent teams. We use the term structured test-time scaling broadly: it encompasses any system that dynamically builds a decoupled computation graph at inference time, rather than extending a single sequential trace. This includes multi-agent teams with explicit role decomposition, but equally covers single-agent recursive architectures (e.g., RLMs
The baseline failure: linear collapse. Simply prompting a model to “think longer” via linear Chains-of-Thought (CoT) forces the sequential span to equal total work ($S = W$), so per-step errors compound as $P_{\mathrm{success}} \approx e^{-\epsilon W}$. This linear collapse is a hard mathematical ceiling on unstructured scaling (Section 2).
The empirical success of structured inference. In practice, the community has bypassed this bottleneck by scaling the system rather than just the context window. Multi-agent frameworks and dynamic reasoning topologies—ranging from static role-playing agent teams
The gap: heuristics vs. theory. Despite their effectiveness, the design of modern agentic systems remains largely driven by heuristics and empirical trial-and-error. System prompts, hierarchical structures, and routing mechanisms are often engineered based on intuition rather than first principles. We lack a unified theoretical framework to explain why certain multi-agent topologies scale reliably, what limits their performance, and how to systematically design them.
Our contribution: A theory of structured test-time scaling. This note bridges that gap. We propose an analytical framework for structured test-time scaling by borrowing the work–span lens from classical parallel computation
- Mechanism I (Topology): Dynamic hierarchy compresses the sequential control span, transforming global drift from a function of total work ($W$) to a function of logarithmic depth ($D$).
- Mechanism II (Scope isolation): Explicit state management actively reduces leaf difficulty and context noise, lowering the intrinsic atomic error rate ($\epsilon_{\mathrm{leaf}}$).
- Mechanism III (Verification): Decoupled filtering (as seen in recent models like Gemini Deep Think’s Aletheia) suppresses the residual error tail ($\delta_+$), preventing undetected atomic failures from propagating into shared state.
Roadmap. Section 2 defines work/span and the linear-collapse baseline. Sections 3–5 develop the three mechanisms. Section 6 synthesizes them into a single reliability scaling law. Section 7 lists the practical constraints that determine whether the gains survive in real systems. Related work is organized as a structural evolution in the appendix.
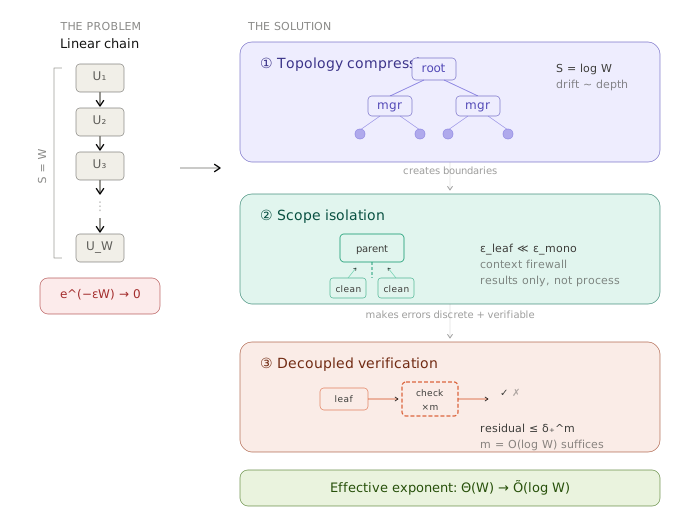
The Baseline: Why Linear Reasoning Collapses
Work and span in test-time compute. Consider a task whose solution requires producing and correctly composing $W$ atomic units (facts, sub-proofs, code edits, tests, etc.). When scaling test-time compute, we distinguish:
- Work $W$: total required atomic units.
- Span $S$: the length of the longest sequential dependency/control path (critical path).
Notation (quick reference).
| Symbol | Meaning |
|---|---|
| $W$ | total atomic units (work) |
| $S$ | sequential control span / critical path |
| $k$ | branching factor / manager fan-out |
| $D$ | hierarchy depth (idealized $\lceil \log_k W \rceil$) |
| $\epsilon_{\mathrm{mono}}$ | unit error rate in monolithic (no isolation) setting |
| $\epsilon_{\mathrm{leaf}}$ | unit error rate after scope isolation at leaves |
| $\eta$ | per-layer drift probability (global intent/spec distortion) |
| $q$ | residual leaf error after all local gates |
| $\delta_+, \delta_-$ | verifier false accept / false reject |
| $m$ | redundant checks per unit |
| $\rho$ | pairwise correlation between retry outcomes |
| $m_{\mathrm{eff}}$ | effective independent checks: $m/(1+(m-1)\rho)$ |
| $c_g, c_v$ | cost of generation / verification |
Linear execution forces $S = W$. A single-agent linear execution induces a sequential chain:
\[U_1 \to U_2 \to \dots \to U_W,\]so the span is $S = W$.
Exponential collapse under small per-step error. Let $\epsilon_{\mathrm{mono}}$ be the probability that a generated atomic unit is incorrect in a way that is not repaired. In the simplest brittle model (independent failures; any critical failure ruins the run),
\[P_{\mathrm{linear}} = (1-\epsilon_{\mathrm{mono}})^W \;\approx\; e^{-\epsilon_{\mathrm{mono}} W}.\]The “physical” limit of the linear topology. To keep $P_{\mathrm{linear}}$ bounded away from $0$ as $W$ grows, one needs $\epsilon_{\mathrm{mono}} = O(1/W)$. That is, the base model would have to become arbitrarily reliable as the horizon lengthens. This is the core brittleness critique of long chains.
The augmented baseline: tools and self-reflection are not enough. Modern single-agent pipelines go beyond naive linear CoT: ReAct
- Span remains $\Theta(W)$. Reflection and tool calls append to the same sequential trace; the critical path still grows linearly with total work.
- Context accumulates monotonically. All reasoning, tool outputs, and reflections share one ever-growing window, so context quality degrades with horizon length and the effective $\epsilon$ rises.
- Verification is neither independent nor explicit. Generator and verifier share the same weights and polluted context, inflating the false-accept rate $\delta_+$ and leaving systematic blind spots uncorrected.
What the baseline teaches. The enemy is not multi-step reasoning per se; it is the linear span that forces errors and drift to accumulate along a length-$W$ control path. If we could reshape the computation graph so that the longest dependency chain is much shorter than $W$, the exponential penalty would shrink dramatically—and any residual errors could be handled locally rather than compounding globally.
Mechanism I: Topology — Compressing the Control Span
From a chain to a tree/DAG. Replace the linear chain with a roughly balanced $k$-ary hierarchy: a manager decomposes work into $k$ subproblems, sub-managers repeat, and leaves produce outputs. In the idealized balanced case,
\[D = \left\lceil \log_k W \right\rceil,\]and the sequential control span scales like $S \approx \Theta(D)$ rather than $\Theta(W)$.
A concrete contrast (linear vs. hierarchical). Hierarchy keeps total work at $\Theta(W)$ but shortens the critical path:
\[\underbrace{\text{Linear: } S=W}_{\text{one long control chain}} \qquad\Rightarrow\qquad \underbrace{\text{Hierarchy: } S \approx D = \Theta(\log_k W)}_{\text{short control depth}}.\]Global drift becomes depth-driven. Let $\eta$ be the per-layer probability that intent or constraints are distorted in a way that is not fully corrected (semantic drift, spec distortion). A simple coherence model is
\[P_{\mathrm{coherence}} \approx (1-\eta)^D \approx e^{-\eta D}.\]Compared to the linear analogue $e^{-\eta W}$, span compression makes drift decay extremely slowly with problem size.
Dynamic Topology as Runtime Compilation (The Control Stack). The balanced tree is a pedagogical idealization. Modern agentic systems construct their topology just-in-time, operating like a dynamic call stack.
- Explicit Orchestration: Frameworks like AOrchestra
formalize the sub-agent not as a fixed role, but as a runtime tuple $\langle \text{Instruction}, \text{Context}, \text{Tools} \rangle$, spawned only when uncertainty peaks. - Recursive Spawning: THREAD
models generation as recursive thread spawning, where each thread can create sub-threads to explore or resolve sub-problems before returning results to its parent. - Implicit Recursion: Recursive Language Models (RLMs)
achieve span compression via functional recursion, where the model invokes itself on sub-problems.
In all these cases, the system trades integration work for reduced span by managing a stack of ephemeral agents, effectively “compiling” the optimal computation graph on the fly.
An important distinction: dynamic topology ≠ topology compression. Not all systems that dynamically reconfigure their communication graph achieve true span compression. Systems like DyTopo
Span is not the whole story. Compressing span tames global drift, but $W$ leaf-level units still must be produced correctly. The next mechanism addresses this by lowering the intrinsic error rate of each leaf.
Mechanism II: Scope Isolation — Decoupling State and Context
Decomposition reduces difficulty, not just latency. Beyond compressing span, decomposition lowers the intrinsic error rate of each subproblem by reducing both difficulty and context noise.
A simple model: error depends on difficulty and noise. Let $L$ denote intrinsic subproblem complexity and $N$ denote context “noise” or distraction. Write the base model’s unit error rate as $\epsilon(L, N)$. A monolithic run tends to induce large $(L, N)$, yielding $\epsilon_{\mathrm{mono}} = \epsilon(L_{\mathrm{root}}, N_{\mathrm{root}})$. A good decomposition aims to create leaves with smaller scope and cleaner context:
\[L_{\mathrm{leaf}} \ll L_{\mathrm{root}}, \qquad N_{\mathrm{leaf}} \ll N_{\mathrm{root}}.\]The motivation is empirical: long contexts degrade reasoning (“lost in the middle”
Isolation is a permanent design principle, not a temporary patch. One might expect scope isolation to become unnecessary as context windows grow. This is incorrect. The function $\epsilon(L,N)$ captures not merely context-length limitations but cognitive bandwidth degradation: as $N$ grows, the signal-to-noise ratio within the context degrades, even if all tokens fit within the window. Empirically, models degrade on needle-in-a-haystack and multi-step reasoning tasks long before hitting hard length limits
Implementing Isolation: External State as a Context Firewall. The unified mechanism behind all forms of scope isolation is an external medium—a file system, a return-value interface, a shared memory store—that serves as a buffer between parent and child computations. The child reasons in a clean, minimal context and writes results, not process to the external medium; the parent reads only the refined output. The child’s reasoning trace is then discarded. This is semantically identical to a function call in programming: local variables are released after return, and the caller sees only the return value. The external medium plays the role of the stack frame and return channel.
Concrete instantiations range from pure to complex. The purest form is RLM’s recursive self-invocation
Regardless of the specific implementation, isolation works by truncating the monotonic accumulation of context via an external medium, ensuring that each inference call operates with $N_{\mathrm{leaf}}$ controlled within the model’s high-reliability regime.
The trade: communication work for lower atomic error. Scope isolation is not free. It converts implicit context attention into explicit coordination work (reading/writing files, managing stack frames). However, it pays for itself by lowering $\epsilon_{\mathrm{leaf}}$ drastically. This explains why dynamic MAS work: they trade cheap token generation (extra work) for a structurally lower error rate (robustness).
Core conclusion: isolation transforms the nature of the error. Beyond lowering the error rate, scope isolation transforms uncheckable global semantic drift into discrete, local, and verifiable failures—a syntax error, a type mismatch, a local logical contradiction. This transformation is not a secondary benefit; it is the structural prerequisite that makes the automated filtering of Mechanism III possible: verification requires errors to be localized, discrete, and independently assessable. Without isolation, errors are diffuse and entangled with global context, rendering verification intractable. With isolation, each leaf output is a self-contained, auditable artifact—precisely the kind of artifact that a compiler, test suite, or independent critic can evaluate. This observation reveals the causal dependency between mechanisms: Topology (Mechanism I) creates the hierarchical decomposition; Isolation (Mechanism II) manufactures verifiable atomic units; Verification (Mechanism III) then exploits this structure to suppress residual errors. Each mechanism creates the structural preconditions for the next.
Mechanisms I–II improve error quality, not error quantity. Neither mechanism reduces the total task count $W$: topology compresses span but preserves $\Theta(W)$ leaves, and fine-grained decomposition can even grow $W$ by fracturing coarse tasks into more atomic pieces. Per-leaf error drops ($\epsilon_{\mathrm{leaf}} \ll \epsilon_{\mathrm{mono}}$), but the number of error opportunities does not—so as $W$ grows, the law of large numbers still guarantees that some leaves will fail, and a single undetected bad leaf can poison upstream state. The system therefore needs a final line of defense: a gate that catches errors before they propagate.
Mechanism III: Verification — Error Correction at the Gates
Why false accept is the system killer. We distinguish two types of verification error:
- $\delta_+$: false accept (accepting an incorrect candidate),
- $\delta_-$: false reject (rejecting a correct candidate).
False reject primarily increases cost via retries. False accept is more dangerous: it seals wrong work into shared state, making later correction difficult or impossible.
The $\delta_+$–$\delta_-$ trade-off and the liveness constraint. Tightening the verification threshold lowers $\delta_+$ but simultaneously raises $\delta_-$—this is the precision–recall trade-off applied to the verification gate. The danger of $\delta_-$ is not merely retry cost: under $m$ redundant checks, a correct candidate survives all rounds with probability $(1-\delta_-)^m$, which decays exponentially in $m$. Thus $m$ is subject to a two-sided constraint—it must be large enough that $\delta_+^m$ suppresses false accepts, yet small enough that $(1-\delta_-)^m$ remains viable. When $\delta_-$ is high or $m$ is large, the system may fail to accept any candidate within a finite retry budget—this is no longer a cost issue but a liveness failure, equivalent to system abort. This is precisely why strict verification systems require an explicit abort mechanism: Aletheia’s “intelligent failure”—outputting “no solution” rather than retrying indefinitely—is an engineering response to the $\delta_-$ liveness constraint.
Two verification regimes. Let $c_g$ be the cost of generating a candidate and $c_v$ the cost of verifying it. Two distinct regimes emerge:
- Classical verification regime ($c_v \ll c_g$): Compilers, type checkers, and test suites verify code at negligible cost relative to generation. Here, heavy redundancy ($m \gg 1$) is cheap.
- Heavy verification regime ($c_v \approx c_g$): Systems like Aletheia
, where verification requires a separate LLM pass of comparable cost. Heavy verification is justified when the cost of a false accept is catastrophic—e.g., sealing a flawed proof step into a long-horizon mathematical argument where downstream correction is impossible.
Crucially, the true necessary condition for verification to provide exponential error suppression is neither $c_v \ll c_g$ nor $\delta_+ < \epsilon_{\mathrm{leaf}}$, but simply:
\[\delta_+ < 1.\]As long as the verifier is not completely blind to the generator’s error modes (i.e., it catches some fraction of errors), redundant checking still achieves exponential suppression $\delta_+^m \to 0$. The difference between regimes is purely one of budget: in the classical regime, $m$ is cheap so aggressive filtering is free; in the heavy regime, the same mathematics holds but each round of $m$ is expensive, so the system must balance verification cost against the catastrophic cost of false accepts.
Redundant checking gives logarithmic suppression. Suppose the leaf generator has unit error probability $\epsilon_{\mathrm{leaf}}$ after scope isolation. Run $m$ independent (or effectively de-correlated) checks and accept only if all checks accept. An incorrect candidate passes with probability at most $\delta_+^m$, so a simple bound on residual leaf error is
\[q \;\lesssim\; \epsilon_{\mathrm{leaf}}\,\delta_+^m.\]To prevent work-driven collapse we want $Wq = O(1)$, i.e.,
\[\epsilon_{\mathrm{leaf}}\,\delta_+^m \;\lesssim\; \frac{1}{W}.\]Solving gives
\[m \;\gtrsim\; \frac{\ln(W\epsilon_{\mathrm{leaf}})}{-\ln(\delta_+)} \;=\; O(\log W),\]so only logarithmically many redundant checks are sufficient under a verification advantage. (This lower bound considers only false-accept suppression; the actual choice of $m$ must also satisfy $(1-\delta_-)^m$ not being prohibitively small, so the optimal $m$ balances both constraints.) Note that this bound requires only $\delta_+ < 1$ (so that $-\ln(\delta_+) > 0$); the verification need not be highly accurate—merely conditionally better than blind acceptance. When $\delta_+$ is close to $1$, the required $m$ grows (since $-\ln(\delta_+)$ is small), but the exponential suppression mechanism still operates. This is why even imperfect LLM-based critics can provide meaningful verification advantage.
Relaxing the independence assumption. The $\delta_+^m$ bound assumes independent verification rounds. In practice, two sources of correlation weaken it: (i) shared systematic blind spots between generator and verifier (e.g., common training biases), and (ii) correlated retries—under fixed temperature and prompt, the generator tends to reproduce similar error patterns across attempts. Let $\rho \in [0,1]$ denote the pairwise correlation between retry outcomes. An exchangeable-Bernoulli approximation gives the effective number of independent checks:
\[m_{\mathrm{eff}} \;\approx\; \frac{m}{1 + (m-1)\rho},\]so residual error degrades from $\delta_+^m$ to $\delta_+^{m_{\mathrm{eff}}}$. When $\rho \to 1$, $m_{\mathrm{eff}} \to 1$ and redundancy provides no suppression. The logarithmic scaling of $m$ still holds, but its constant factor depends on de-correlation quality. This reframes the de-correlation strategies below—diversified prompts, temperature variation, cross-model critics, tool-based checks—as necessary conditions for the exponential suppression to operate at its theoretical rate.
Error mode orthogonality: the design principle behind de-correlation. The deeper principle underlying these strategies is error mode orthogonality: verification advantage arises when the verifier’s failure modes are orthogonal to the generator’s. A compiler cannot write code, but it catches every syntax and type error—its error modes are perfectly orthogonal to the generator’s syntactic failures. A test suite cannot reason about intent, but it catches every functional regression. Even an LLM-based critic provides verification advantage if it is prompted, fine-tuned, or architecturally separated so that its blind spots differ from the generator’s. The key insight is that verification advantage is fundamentally about complementary competence, not about verifier accuracy or cost per se.
Case Study: Decoupling for Strict Verification (Gemini’s Aletheia). The necessity of minimizing $\delta_+$ is central to recent breakthroughs in inference-time scaling for scientific reasoning, such as Google DeepMind’s math-research agent Aletheia, built on Gemini Deep Think
Coding agents: the classical verification regime in action. Software development provides the cleanest instantiation of the classical verification regime. When a coding agent generates a function implementation, a compiler provides a verifier with $\delta_+ \approx 0$ for syntactic and type errors (it literally cannot false-accept ill-typed code), and a test suite provides $\delta_+ \approx 0$ for covered functional specifications. The cost ratio satisfies $c_v \ll c_g$: running a test suite takes milliseconds, while generating a candidate implementation may require substantial LLM inference. The evolutionary trajectory of coding agents confirms the framework’s predictions: early systems relied primarily on verification advantage, and more recent designs—such as Claude Code’s sub-agent mechanism
A Unified Theory of Reliability
Two failure channels: drift vs. residual leaf errors. With all three mechanisms in hand, we can now unify them into a single reliability model. The system faces two independent failure channels: global drift (span/depth-driven) and local residual error (work-driven). Modeling them as independent yields a multiplicative decomposition:
\[P_{\mathrm{success}} \;\approx\; \underbrace{\exp\!\big(-\eta D\big)}_{\text{survive drift}} \;\times\; \underbrace{\exp\!\big(-W q\big)}_{\text{survive leaf errors}}.\]The first factor is the probability that global intent survives $D$ layers of hierarchical delegation; the second is the probability that no residual leaf error poisons the final output. Taking logarithms gives the additive form:
\[-\ln P_{\mathrm{success}} \;\approx\; \underbrace{\eta D}_{\text{span / drift}} \;+\; \underbrace{W q}_{\text{work / residual}}.\]Substituting the verification bound $q \lesssim \epsilon_{\mathrm{leaf}} \delta_+^m$ yields the “three-layer” decomposition:
\[-\ln P_{\mathrm{success}} \;\approx\; \underbrace{\eta D}_{\textbf{Topology (span)}} \;+\; \underbrace{W \epsilon_{\mathrm{leaf}}}_{\textbf{Scope isolation (node error)}} \;\times\; \underbrace{\delta_+^m}_{\textbf{Verification (filter)}}.\]Synthesis: The Structural Decoupling of Inference. The unified equation reveals that reliable MAS do not simply “add more compute”—they succeed through strict structural decoupling. Unstructured CoT entangles control flow, state memory, and error checking into a single, fragile context window. Structured scaling dismantles this monolith: Topology decouples control flow from work; Isolation decouples ephemeral reasoning from persistent state; Verification decouples the generator from the critic.
The causal chain: Topology → Isolation → Verification. The three mechanisms are not independent design choices that happen to combine additively. They form a causal dependency chain in which each mechanism creates the structural preconditions for the next:
- Topology enables Isolation. Without hierarchical decomposition, the system operates in a single monolithic context where all state is entangled. Topology (Mechanism I) creates the boundaries—sub-agents, function calls, recursive invocations—across which scope isolation can be enforced.
- Isolation enables Verification. Without scope isolation, errors manifest as diffuse semantic drift entangled with global context—exactly the kind of failure that no verifier can reliably detect. Isolation (Mechanism II) transforms errors into discrete, localized, verifiable artifacts: a function that either passes its tests or does not, a sub-proof that either type-checks or does not. Only then can Mechanism III’s exponential suppression $\delta_+^m$ operate.
This chain explains why bolting verification onto a monolithic system provides limited benefit (the errors are not verifiable), and why decomposition without verification still suffers work-driven collapse (the errors are verifiable but unchecked). The full reliability gain requires all three layers in sequence.
Regimes (why “no heavy verification” can still work). The same equation explains an empirical spectrum:
- Isolation-dominated regime: if $W \epsilon_{\mathrm{leaf}}$ is not large on the workload, modest or even zero explicit checking can succeed.
- Verification-dominated regime: if $W \epsilon_{\mathrm{leaf}}$ becomes large, the system must grow $m$ so that $\delta_+^m$ drives $q$ down to $O(1/W)$.
Empirical validation: mapping existing systems. The table below applies the three-mechanism framework to a representative cross-section of inference-time scaling approaches. The progression from top to bottom mirrors a gradual engagement of structural mechanisms: linear CoT engages none (the $S=W$ baseline), while dynamic orchestration and recursive architectures activate topology and isolation but leave verification implicit. Most systems inhabit a different structural “sweet spot” with characteristic gaps. The framework predicts that convergence toward the full three-layer architecture is the path to reliable scaling.
| Inference Pattern | Representative Systems | I | II | III |
|---|---|---|---|---|
| Linear CoT / Tool Use | CoT, ReAct | — | — | — |
| Self-Reflection Loops | Reflexion, Self-Refine | — | — | ○ |
| Breadth Search / Sampling | Self-Consistency, ToT, GoT | — | ○ | ○ |
| Planning + Search | LATS | — | ○ | ○ |
| Static Role Teams | CAMEL, MetaGPT, ChatDev, AutoGen | ○ | ○ | ○ |
| Dynamic Orchestration (hierarchical) | AOrchestra | ● | ● | ○ |
| Dynamic Orchestration (peer-topology) | DyTopo, DyLAN | ○ | ○ | ○ |
| Recursive LM | RLM | ● | ● | ○ |
| Recursive Threading | THREAD | ● | ○ | ○ |
| Coding Agents (tool-verified) | SWE-agent, Claude Code, Codex | ○ | ● | ○ |
| Dual-Layer Verification Agent | MiroThinker-H1 | ○ | ● | ● |
| Strict Decoupled Verification | Aletheia (Gemini Deep Think) | — | ○ | ● |
Mechanism coverage of inference patterns. I = Topology (span compression), II = Scope isolation, III = Decoupled verification. ● = structurally present, ○ = implicit or partial, — = absent. The horizontal rule separates single-context approaches (top five) from multi-context structured approaches (bottom six). Dynamic orchestration systems are split into two rows: AOrchestra implements genuine hierarchical spawning with explicit context curation and file-system isolation (●● for Mechanisms I–II), whereas DyTopo and DyLAN optimize dynamic communication routing among flat peer agents without hierarchical decomposition or external-medium context firewalling (○○). RLM and THREAD are listed separately: RLM achieves true topology compression and scope isolation with implicit verification, while THREAD provides true topology compression but only implicit isolation and verification. Coding agents provide implicit topology compression and verification but explicit scope isolation. MiroThinker-H1 provides implicit topology compression but explicit scope isolation and dual-layer local and global verification. The framework predicts that convergence toward the full three-layer architecture is the path to reliable scaling.
Practical Constraints
Hierarchy is not a free lunch. The following constraints determine whether the scaling story behind the unified equation survives contact with reality.
Constraint 1: Managerial capacity (bandwidth and fan-out limits)
A manager must orchestrate sub-agents through a low-bandwidth interface: $\mathrm{Comm}(u \to v) \le B$. If modules require exchanging full internal state (strong coupling), coordination cost explodes, negating span compression.
Crucially, this bottleneck extends to the branching factor ($k$). One might assume that external storage (Mechanism II) eliminates the bottleneck on $k$, as a manager can write $k$ sub-tasks to a file system without overflowing its context window. However, this conflates storage capacity with semantic integration capacity. To produce a coherent global decision, the manager must synthesize $k$ distinct logical branches—an $O(k)$ reasoning task rigidly bounded by the base model’s active attention capacity. Pushing $k$ to the extreme simply shifts the linear collapse back onto the manager. Therefore, bounded bandwidth and bounded fan-out jointly dictate that deep hierarchies ($D > 1$) are mathematically necessary for large $W$.
Constraint 2: Scope isolation boundaries (active atomic tractability)
The system must actively manufacture tractable leaves by isolating scope and cleaning context:
- Context hygiene: keep $N_{\mathrm{leaf}}$ low (avoid long noisy threads).
- Complexity reduction: keep $L_{\mathrm{leaf}}$ within the base model’s reliable regime.
- Non-leaky boundaries: prevent irrelevant constraints and unvetted partial solutions from leaking across modules.
If scope isolation fails, $\epsilon_{\mathrm{leaf}}$ rises toward $\epsilon_{\mathrm{mono}}$, pushing the burden back onto heavy verification.
Constraint 3: Verification advantage (correctness, efficiency, and design)
The verification mechanism requires three conditions, ordered by necessity:
- Correctness ($\delta_+ < 1$): The verifier must not be completely blind to the generator’s error modes. This is the true necessary condition—without it, redundant checking provides no suppression regardless of budget.
- Efficiency ($c_v$ determines regime and budget): The cost ratio $c_v / c_g$ determines how many rounds $m$ the system can afford. In the classical regime ($c_v \ll c_g$, e.g., compilers), $m$ is essentially free; in the heavy regime ($c_v \approx c_g$, e.g., Aletheia), $m$ is expensive but justified by catastrophic failure costs.
- Design (error mode orthogonality determines $\delta_+$): The achievable $\delta_+$ level depends on how orthogonal the verifier’s failure modes are to the generator’s. This is an architectural design choice, not a fixed property of the verifier alone.
Conclusion
Long-horizon reasoning fails not because base models make errors, but because unstructured topology ($\Theta(W)$ span) forces those errors to compound exponentially. This note has shown that the empirical success of structured inference systems—from multi-agent teams to recursive architectures to coding agents—follows from structured test-time scaling: topology compression, scope isolation, and decoupled verification jointly attack all three failure channels—drift, atomic error, and residual tails—reducing the effective exponent from $\Theta(W)$ to $\tilde O(\log W)$. Crucially, these three mechanisms form a causal chain (Topology → Isolation → Verification), each creating the structural preconditions for the next, rather than operating as independent, additive improvements. The next frontier of reliable reasoning lies in rigorous, theory-guided design of the inference-time computation graph.
Acknowledgements
We thank Hao Sun and Alex Zhang for feedback and helpful comments. We also thank Qiang He, Jinfa Huang, and Tong Chen for reading and helpful comments. We thank Weijie Su for discussion. We thank Sara Mostafavi for support.
Related Work
We organize related work as a structural evolution in how inference-time computation is arranged, viewed through the work–span lens. Our work–span decomposition builds on classic parallel-computation results
Phase I: Static pipelines and role-fixed teams
Early MAS mimic fixed organizational charts: CAMEL
Phase II: Inference-time search and internal deliberation
Within a single context, CoT
Phase III: Dynamic and recursive topology
Systems now construct their computation graph at runtime. These systems differ in the kind of dynamism they employ, which determines their mechanism engagement. AOrchestra
Verification, debate, and fault-tolerance
Debate
Relationship to sparse attention
Sparse attention mechanisms—sliding windows, dilated patterns, block-sparse masks—address the same context-dilution problem as Mechanism II. From this angle, MAS implements inference-time sparse attention: each agent’s context window acts as an attention mask and the orchestrator determines the sparsity pattern. The key difference is adaptivity. Static sparse patterns are fixed at architecture design time; linear attention and state-space models (e.g., Mamba) add input-dependent gating but remain fixed in mechanism and confined to a single forward pass. MAS constructs its sparsity pattern dynamically at runtime, conditioned on problem structure, and can spawn independent sub-contexts mid-computation. Moreover, MAS operates across separate context windows ($k$ agents $\times$ $n$ tokens each), whereas all sparse attention variants require information to reside within a single sequence. Finally, MAS couples adaptive sparsity with verification gates at every aggregation point (Mechanism III)—a structural bonus absent from any single-pass attention scheme. The two approaches are complementary: sparse attention optimizes information flow within a forward pass; structured test-time scaling optimizes it across multiple inference calls.
Synthesis
Table 1 (in the Unified Theory section above) maps each of the above inference patterns onto the three structural mechanisms. Most existing approaches leave at least one mechanism unengaged.